Side by side
| Bare-metal server (SSH) | Managed pod (web UI) | |
|---|---|---|
| What you get | Whole physical server, not shared | A container on a shared or partner host |
| Access | SSH, Jupyter, any image | Web console, template images |
| Multi-GPU | All GPUs in the node with NVLink (H100, H200) | Depends on the host and template |
| Setup effort | You manage drivers, containers and storage | Minutes from a template |
| Best for | Training runs of days, production serving | Short tests, demos, one-off jobs |
Why bare metal suits LLM work
- No noisy neighbours. The node is yours, so throughput and latency stay predictable during a multi-day run.
- Full interconnect. An 8× H100 or H200 node links GPUs with NVLink at 900 GB/s, which tensor-parallel serving and sharded training depend on.
- Your stack, your versions. Run vLLM, SGLang, TensorRT-LLM or your own container without waiting for a template update.
- Data stays on known hardware. You choose the region; dedicated servers are not shared with other customers.
The honest downsides
Bare metal asks more of you: you install and update your images, set up storage and monitoring, and stop the server yourself when work ends. For a quick test of a 7B model, a pod from RunPod or a Vast.ai listing is often cheaper and faster to start. At Strata, servers come with PyTorch and CUDA images and our engineers help with the first deployment, which removes most of the setup gap.
What it costs at Strata
| GPU | On demand, per GPU-hour | 24–36 month reserved |
|---|---|---|
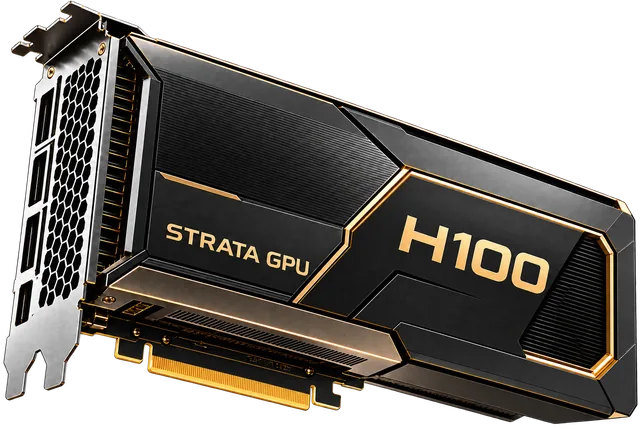
| H100 80GB | $3.23 | $2.78 |
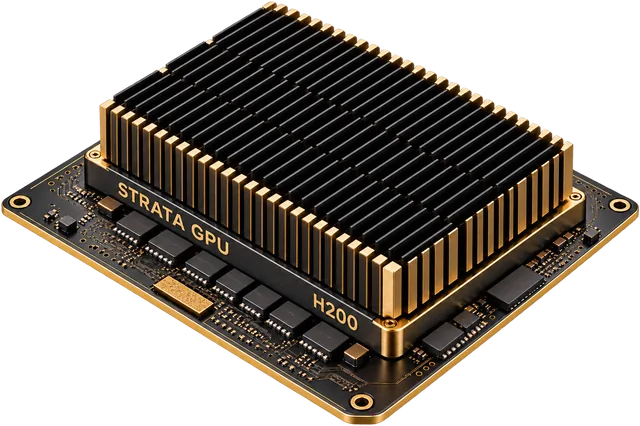
| H200 141GB | $4.31 | $3.71 |
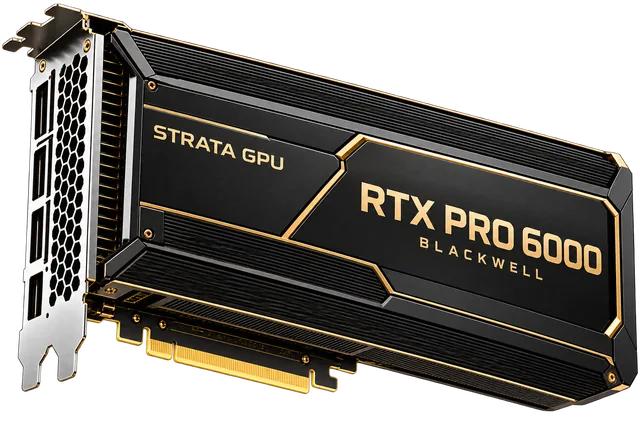
| RTX PRO 6000 96GB | $2.03 | $1.75 |
Strata GPU list prices as of 2026-11-03. On demand is billed per minute; reserved clusters start at one 8-GPU node for 3 months.