Specifications
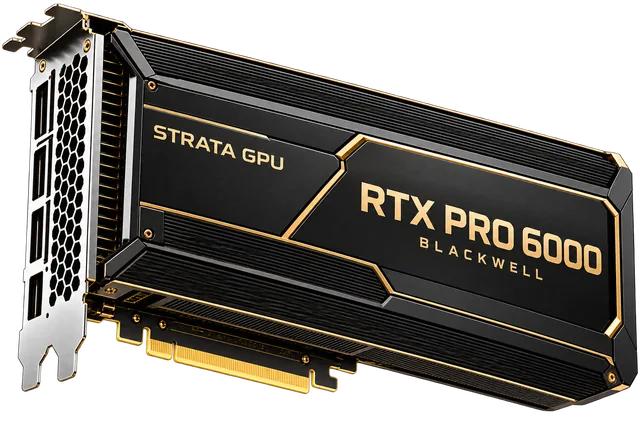
What the RTX PRO 6000 is best for
- Inference of 7B–70B models with quantization
- Image and video generation: Flux, SDXL, Wan, Hunyuan
- LoRA and QLoRA fine-tuning
- Rendering and mixed graphics plus AI workloads
How renting works
On-demand GPUs start in minutes and are billed per minute from a prepaid balance. Dedicated RTX PRO 6000 clusters are allocated to you alone for 3 to 36 months at a lower, locked rate. Pay by card, bank transfer, USDT or USDC.
Compare
Questions
Where can I rent an RTX 4090 or RTX 5090 GPU? Strata GPU vs RunPod: which one should I use? Strata GPU vs Vast.ai: which is better for renting GPUs? What is the cheapest way to rent H100 GPUs? What GPU do I need to run Llama 70B or another 70B model? How do I rent a GPU server for AI? A step-by-step guide What happens if on-demand GPUs are unavailable? Get 1-hour H100 access for benchmarks How to stop paying for idle rented GPUs (and surprise bills) Bare-metal SSH GPU server vs managed GPU pod for LLMs Cloud GPUs for self-hosting ComfyUI (images and video) Which GPU to rent for models needing 80 GB, 130 GB or more VRAM How to stop re-downloading model weights on rented GPUs GPU and network volume in different datacenters: how to avoid it Rent H100 and H200 GPUs in Asia-Pacific: Singapore, Tokyo, Mumbai